




Browser trust, HTTP speed

SERP API-style JSON

Completely free

Open source, MIT license
01
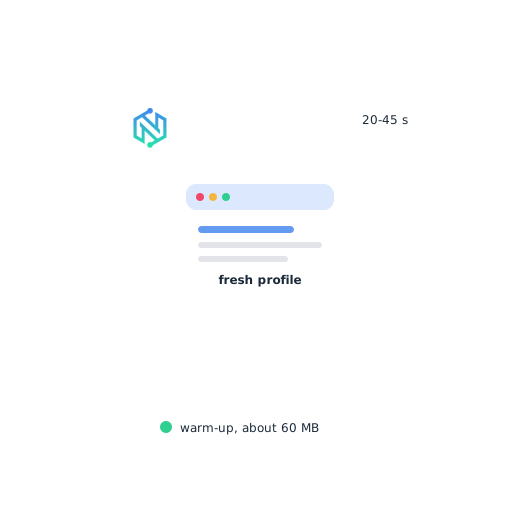
The scraper opens a sticky proxy session and a fresh browser profile. Chrome then visits a few ordinary pages and stays on each for 20 to 45 seconds. This collects the cookies Google trusts. A fresh warm-up uses about 60 MB, so the first query takes a few minutes. Later queries on the same proxy IP take about 1.4 seconds
02
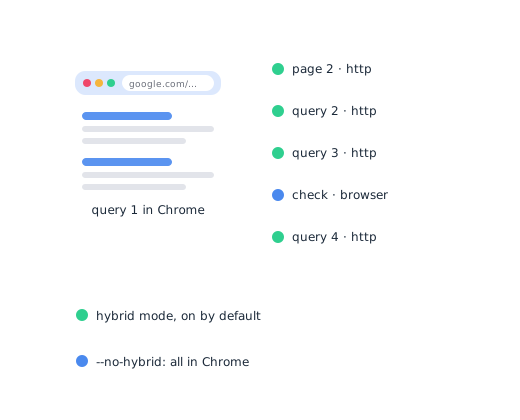
Hybrid mode is on by default. The first query on a proxy IP opens Google’s results page in Chrome. The next results pages come over light HTTP requests with Chrome’s cookies, and the browser steps back in when Google checks again. Add --no-hybrid and every search runs in a full Chrome window
03
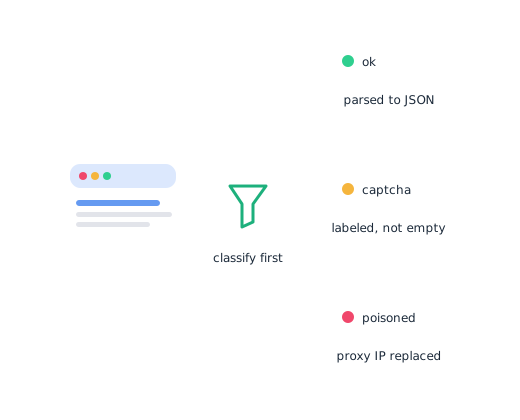
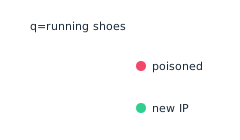
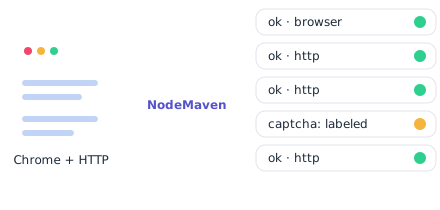
Every page is classified first. CAPTCHAs and refusals are reported as such. Poisoned results, where Google serves results for a different query, are detected and the proxy IP is replaced. Only real results reach your data
04
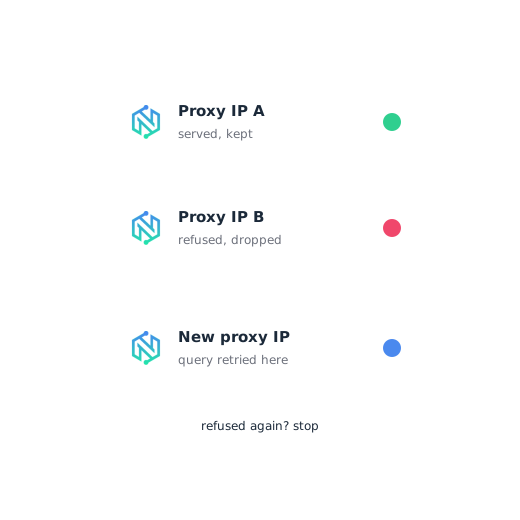
A proxy IP Google serves is reused for the next queries. A refused proxy IP is dropped, and the query is retried on a new one. If proxy IPs keep getting refused, the run stops instead of spending more traffic

Install
Install the Python package with NodeMaven support, then add the Chromium browser it runs on. It takes two short commands

Connect NodeMaven
Add your NodeMaven login and password to your environment. The scraper reads them and manages proxy sessions for you

Run your first search
Put your keywords in a text file and start a search. You get one JSON record for every Google results page
Poisoned results caught
Google sometimes serves bots results for a different query. The scraper catches them and replaces the proxy IP, at no extra traffic
Cost counter
Each run ends with pages served, traffic used and the hosts that used it. Add --price-per-gb and the scraper prints the cost per 1,000 pages
NodeMaven built in
NodeMaven residential proxies connect with one flag: --nodemaven. Sessions and credentials are handled for you. Set language and country with --hl and --gl
AI overview and places
Each record includes Google’s AI Overview when an English results page shows one. Local queries also return places from the map, with rating, address and opening hours
Hybrid or full browser
Chrome passes Google’s checks, then results come over HTTP with its cookies. If that fails, the browser takes over. --no-hybrid runs every search in Chrome
Free and open source
MIT-licensed code you can read, fork and run yourself. No subscription or per-search fees, just proxy traffic
Cost per search
Tested in hybrid mode, the default. Multiply the traffic by your NodeMaven price per GB to get the cost of 1,000 searches
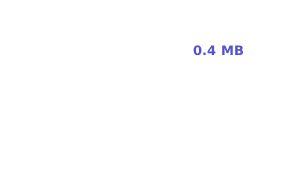
0.4 MB
per search without warm-up
1.4 s
per search on a warm proxy IP
~0.45 GB
per 1,000 searches on long runs
~60 MB
per fresh warm-up
Cookie copies
New proxy IPs start from the cookies of a proxy IP Google already serves. A copy costs a few MB instead of a full warm-up. It waits 40 to 60 seconds before its first search.
10
copied proxy IPs by default
180 min
cookie lifetime
40-60 s
start delay
Few MB
per copy
Long runs
Served proxy IPs stay in use for hundreds of queries. Regular browser restarts keep memory flat over long holds

300
queries per proxy IP
50
pages between restarts
1
retry on a browser error
N
parallel workers
The plain HTTP approach
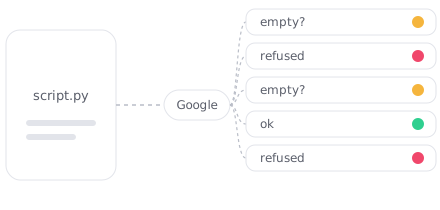
A script sends raw requests and parses whatever HTML comes back. Google often expects JavaScript, so responses are unreliable. A refused page can be parsed as an empty result. You cannot tell "no results" from "refused"
The Google Search Scraper approach
Each proxy IP is warmed up in real Chrome on a sticky session. In hybrid mode, the default, Chrome passes Google’s checks and results pages then come over HTTP with its cookies. With --no-hybrid, every search runs in Chrome. Every page is classified before parsing. Refused pages come back labeled, and the proxy IP is replaced

SEO monitoring
Track positions for your own keywords and watch how results change. Run keyword and competitor research on live Google results
Recommended for:

AI agents and LLM apps
Give Claude, Cursor and other agents live Google search through the MCP server. Each call returns structured results, not raw HTML
Recommended for:

Not sure which mode fits your project?


